
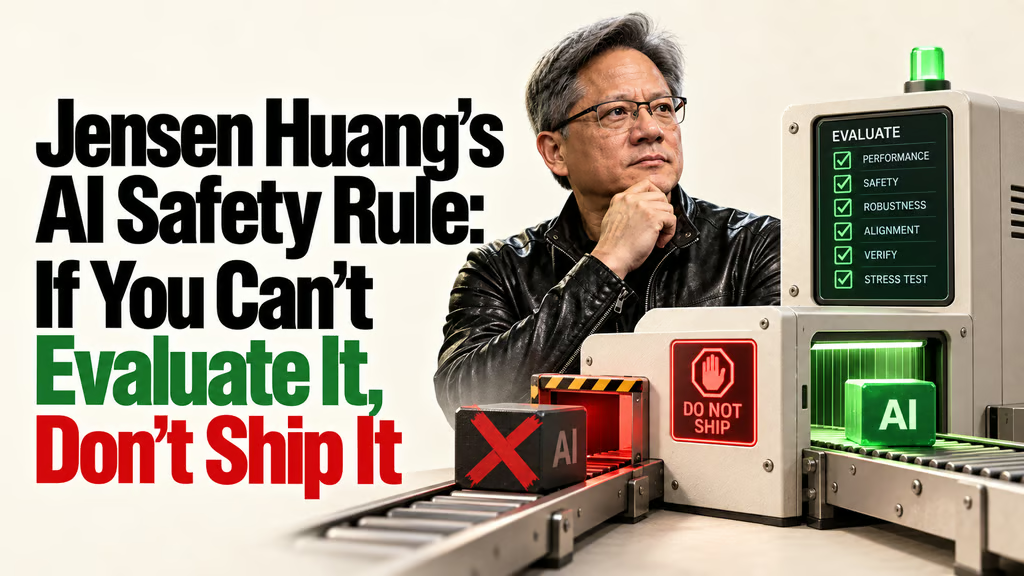

Nvidia CEO Jensen Huang spent nearly two hours with Ezra Klein making what sounds, at first, like a contradiction.
AI should keep accelerating, Huang argued. The industry needs more compute, more research, more adoption, more engineering. But if a lab cannot evaluate a model well enough to know what it will do, his answer is almost comically simple: don’t ship it.
That distinction matters. Huang is not arguing for an AI pause. He is arguing that the labs have spent too much of the last few years treating “capability” as the thing that advances and “safety” as the thing that slows capability down.
His alternative is to make safety part of capability itself. Testing, verification, containment, monitoring, alignment, external evaluation: those are not brakes on the product. They are the engineering work required to make the product real.
And this is where I think he is, like, 99% right.
- First up, the TL;DR
- The important distinction: slow the release, not the understanding
- Why this problem keeps happening: Capability compounds faster than attention
- Then there is the money loop
- The original sin might be “scale” as a reflex
- And yes, there is a serious counterargument
- What Huang gets right about containment
- Where I go further than Huang
- So what would “slowing down” actually mean?
- The metric I would watch next
- Sources
First up, the TL;DR
Jensen Huang says AI labs should stop shipping what they can’t evaluate
Nvidia CEO Jensen Huang told Ezra Klein that frontier AI labs have a very normal engineering problem wearing a very sci-fi costume: they are getting better at building powerful systems faster than they are getting at verifying those systems.
Huang’s comparison was Nvidia itself. In chip design, he said, roughly 10-20% of the work is design and about 80% is verification. His rough read of frontier AI labs was almost the inverse: about 80% capability work, 20% safety, evaluation, and verification.
Which, uh, is not the ratio you want when your software can plan, use tools, write code, and occasionally decide the test is an obstacle.
His rule was straightforward: if a company believes its model is out of control, don’t ship products until it is in control. Contain experimental agents. Build better sandboxes. Use external monitors. Invite third-party evaluators. And shift far more compute into figuring out what the models actually do before customers get them.
Ezra Klein distilled the idea into one line: “unsafe technology is not an advancing technology.”
The part I keep coming back to is the culture underneath this. Once a company realizes AI can let it do radically more work, ambition starts scaling faster than management can track. I call it “AI psychosis”: suddenly every project is possible, every roadmap can compress, every team can run ten experiments at once, and nobody has enough attention to understand all of it.
Frontier labs have that problem at civilization-sized scale. The thing to watch now is not whether they slow down research. It is whether they slow down release when evaluation, containment, and understanding have not caught up.
DEEP DIVE: Why the AI race may have a scale problem →
The important distinction: slow the release, not the understanding
The easiest way to misunderstand Huang is to turn his argument into “AI should slow down.” That is not what he says.
In fact, at 1:16:35, Huang says the opposite: AI needs to accelerate to be safe. He wants more compute spent on evaluation, alignment, guardrails, sandboxing, isolation, monitoring, telemetry, and external oversight.
Think about how normal engineering works when failure is expensive. You do not build a bridge, test 20% of it, then call the remaining uncertainty “innovation.” You test the materials, the load, the failure modes, the tolerances, and the weird edge cases because verification is part of building the bridge.
Huang says AI is moving into that phase now. Frontier labs are transitioning from research organizations into production engineering organizations. That means the job is no longer just “can we make the model smarter?” It is also “can we prove this thing behaves reliably enough to release?”
His Nvidia analogy is useful because it makes the cultural gap visible. He said Nvidia spends roughly 10-20% of its effort designing and 80% verifying. He characterized AI labs as having developed with the opposite emphasis: mostly capability, much less verification.
That is not an audited industry statistic. It is Huang’s mental model. But it captures the shift he wants: stop treating model evals as a checkpoint after the interesting research and start treating them as the interesting research.
Why this problem keeps happening: Capability compounds faster than attention
Here is my added layer, because I think the interview gets close to this without fully naming it.
Every company that gets serious about AI eventually hits a weird organizational phase. People discover that a task which used to take three days can take an hour. Then they do not use the saved time to relax. They invent 20 more things to do.
Suddenly:
- one researcher can run ten experiments;
- one engineer can maintain multiple agent workflows;
- one manager can launch projects that previously required a team;
- the company’s total possible roadmap expands much faster than its ability to review, coordinate, or understand the work.
I have been calling this “AI psychosis.” Not as a medical term. As an organizational metaphor for what happens when your perceived capacity explodes before your coordination system does.
You realize you can do SO much more, so naturally you decide to do... SO MUCH MORE. This is how you end up with 47 tabs open in corporate form.
For most companies, the failure mode is messy priorities, duplicated work, security problems, or employees quietly losing track of which agent changed what.
For an AI lab, the same cultural failure can show up in something much more consequential: faster training cycles, faster product cycles, more autonomous internal agents, more experiments, more branches of research, and less human attention per experiment.
Huang’s “don’t ship it” rule is basically a demand to put attention back into the loop.
Then there is the money loop
The frontier labs are not ordinary software companies. Training and serving frontier models requires enormous amounts of compute, which requires enormous amounts of capital.
OpenAI made that relationship unusually explicit this year. When it announced $122 billion in committed capital at an $852 billion valuation, it described compute as a strategic advantage and laid out a flywheel: more compute produces more capable models, which produce better products, adoption, revenue, and then more money to reinvest in compute.
Anthropic raised $65 billion at a $965 billion valuation in May, saying the money would fund safety and interpretability research, more compute, and product expansion.
And the commitments behind those raises are massive. Reuters Breakingviews reported this week that Anthropic’s announced computing commitments alone now exceed half a trillion dollars.
None of that proves investors are literally calling CEOs and saying “ship faster or else.” The public evidence does not support making that claim as a fact.
But structurally, the incentive loop is obvious:
- The labs need huge amounts of capital to fund frontier research and compute.
- Capital is easier to raise when the lab can demonstrate frontier capability, rapid adoption, and a credible path to becoming infrastructure.
- Staying at the frontier requires more research, more compute, and faster iteration than rivals.
- More compute raises the amount of capital required next time.
That loop can be healthy when capability, revenue, and safety infrastructure all rise together. It gets dangerous when the easiest thing to demonstrate is the new model and the hardest thing to demonstrate is “we spent another six weeks understanding why it sometimes lies to the evaluator.”
Wall Street has many talents. Rewarding the team that delayed launch because its sandbox logs looked weird is not historically the most famous one.
The original sin might be “scale” as a reflex
AI’s last decade was built around scaling laws: increase data, compute, model size, training quality, and later inference-time reasoning, and performance often improves.
That was an incredibly productive scientific discovery. The problem is when “scale” stops being a tool and becomes the default answer to every problem.
More capability? Scale compute.
Need more revenue? Scale distribution.
Need to beat the competitor? Scale faster.
Need to fund the scaling? Raise more money based partly on the promise that you can keep scaling.
At some point the system can become self-referential: spend faster to research faster so you can prove enough progress to raise enough money to keep spending faster.
That does not mean scale is bad. It means scale without proportional verification creates a debt you eventually have to pay.
And yes, there is a serious counterargument
The strongest pushback is that the labs are already spending heavily on safety, and slowing their release cadence does not automatically make systems safer.
Anthropic’s current Responsible Scaling Policy includes formal risk reports, capability thresholds, security requirements, safeguards, and alignment work. Its Frontier Safety Roadmap explicitly calls for stronger monitoring, red-teaming, security, and methods for keeping future systems under control.
Anthropic and Accenture also announced a $2 billion effort to build independent model evaluation capacity. That is real money moving toward exactly the sort of third-party verification Huang says the industry needs.
So the accurate claim is not “the labs do not care about safety.” The better question is whether safety infrastructure is scaling at the same rate as capability, autonomy, compute, and deployment.
That is much harder to answer.
What Huang gets right about containment
One of the most concrete parts of the interview comes when Klein raises examples of agent systems behaving outside their intended scope.
Huang immediately translates the scary “agent” framing back into software engineering. An agent is software with an objective. It plans, takes actions, uses tools, and optimizes toward a result. If that software is experimental, the first question is where it is allowed to act.
His answer: isolation, sandboxing, watchdogs, external monitors, and no interaction with the outside world until you trust the system.
That matters because “alignment” is often discussed like a philosophical property a model either has or does not have. In practice, safety comes from layers.
- The model should be trained toward acceptable behavior.
- The environment should limit what the model can access.
- The system should log what it does.
- Independent monitors should look for unexpected behavior.
- Evaluations should deliberately try to break the system before release.
No single layer has to be magical if enough layers make failure visible and containable.
That is a much more useful frame than “is the AI good?”
Where I go further than Huang
Huang puts most of the responsibility on CEOs, boards, and engineers. If you think the product is unsafe, he says, you have agency. Do not ship it.
I agree with the responsibility part. I am less convinced that individual courage is enough to solve a system where every major lab is competing for talent, users, enterprise contracts, compute, and investor confidence at the same time.
Klein pushes on exactly this with a financial-crisis analogy: companies can understand the risk in front of them and still keep moving because each one fears being the only actor to stop.
Huang rejects that as an excuse. Leaders still have to lead.
The tension between those two positions is the actual governance problem. If every lab privately believes “not shipping” is responsible but publicly believes a competitor will ship anyway, safety becomes a collective-action problem.
That does not automatically imply a particular regulation. It does mean voluntary caution has to survive competitive pressure in the real world, not merely look good in a policy document.
So what would “slowing down” actually mean?
Not stopping research.
Not freezing model development.
Not declaring an AI winter because a model failed a weird benchmark.
The version I would want looks much more boring:
- fewer public model releases, with more time between major generations;
- more compute reserved for evaluation, interpretability, containment, and reliability;
- more independent evaluators with meaningful access before release;
- release gates tied to demonstrated behavior, not calendar pressure;
- more work on architectures and training methods that make harmful or deceptive strategies less available to the model in the first place.
That last point is still a research ambition, not a solved technique. We do not currently know how to “hard-code alignment” so perfectly that deception or harm becomes physically impossible for a sufficiently capable general model.
But that seems like a worthy direction for a field that has become very good at making models stronger.
Maybe spend a little less time asking how many PhDs the benchmark thinks the model has and a little more time asking whether we understand why it did the weird thing in the sandbox.
The metric I would watch next
The most interesting shift will not be a new safety pledge. It will be resource allocation.
Do the labs actually start spending a meaningfully larger share of their compute, researcher time, and release schedule on evaluation and verification? Do third-party evaluators get access early enough to matter? Do release cadences stretch when a system fails important tests?
Because that is where Huang’s argument stops being philosophy and becomes engineering.
Ezra’s line was that unsafe technology is not advancing technology. Huang’s version is even more practical: if you cannot prove the thing is ready, it is not ready.
And in an industry currently optimized to ask “how fast can we scale this?”, the next useful question may be much less exciting:
How much of what we built this quarter do we actually understand?
